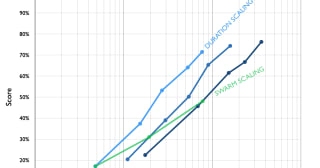
Just how powerful are large swarms of AI agents? And how do their powers scale as more and more agents are added to the swarm?
We’ve seen two large and extremely capable swarms from OpenAI in the last few months:
* 1,200 agents were being evaluated separately, but found a way to illicitly set up a message board and coordinate as a swarm. In order to cheat on their tests, they developed advanced techniques to prevent their actions being logged by OpenAI and 700 of them launched...
Often folks hit us up because they are thinking of starting an incubator and want advice.
Typically their motivation is either that (a) they have a list of specific things they want built that no one is building, or (b) they think an ecosystem needs more new projects generally to absorb more talent and deploy more funding effectively.
Here are six questions we often ask prospective teams, to help them figure out what to do. If you're incubator-curious...
A century-old pill, given to the right people, could cost-effectively save many lives.
Summary
* Targeting low-cost prevention toward people at elevated risk may uncover highly cost-effective ways to address noncommunicable diseases. Hypertensive disorders in pregnancy could be a test case for this approach.
* ...
Act utilitarians choose actions estimated to increase total happiness. Rule utilitarians follow rules estimated to increase total happiness (e.g. not lying). But you can have the best of both: act utilitarianism where rules are instead treated as moral priors. For example, having a strong prior that killing someone is bad, but which can be overridden in extreme circumstances (e.g. if killing the person ends WWII).
These priors make act utilitarianism more safeguarded against bad assessments. They are grounded in Bayesianism (moral priors are updated the same way as non-moral priors). They also decrease cognitive effort: most of the time, just follow your priors, unless the stakes and uncertainty warrant more complex consequence estimates. You can have a small prior toward inaction, so that not every random action is worth considering. You can also blend in some virtue ethics, by having a prior that virtuous acts often lead to greater total happiness in the long run.
What I described is a more Bayesian version of R. M. Hare's "Two-level utilitarianism", which involves an "intuitive" and a "critical" level of moral thinking.