Quick takes
Thoughts on the American legal system
This adversarial model of prosecution vs defense is a bad set up. It encourages the prosecution and indeed police to cut all corners possible on the way to a verdict and we know this happens quite a lot with very little consequence. The prosecution also insists on pursuing cases that have clearly been shown in later years to be false convictions because they want to save face and not admit they got details wrong. A better justice system is built of two sides working together to find the truth and having avenues for admi...
I've had a vague sense that the EA Forum is declining in quality posts/conversation despite having lots of posts, so had an AI tool (Astra) do a bunch of random analyses to look at various measures of activity level, and I think these vaguely confirm my sense. In particular, there has been a decline in commenting from higher karma users, and fewer posts are getting lots of upvotes, despite lots of people still posting. As a lover of the Forum, this seems bad and sad.

Is it harmful to keep your money in index funds? Let's take a random index fund like FTSE Global All Cap Index Fund. If we look at the companies it actually invests in, a lot of them are the same companies that work towards advancing the AI.
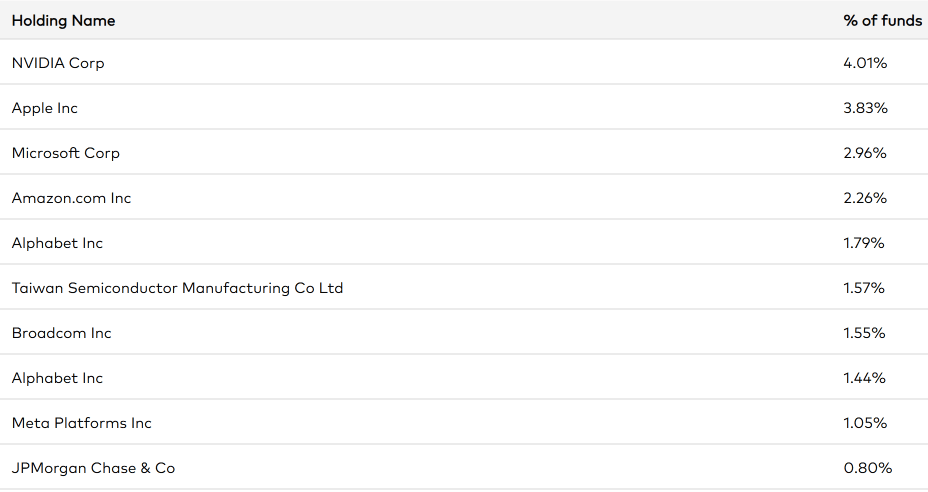
It would be ironic for some of us to be in favour of pausing AI and invest money into it at the same time. I used to keep some of my money in such funds because that was always the financial advice for regular folk like me who don't know/think much about investments. But now I don't know what to do because this fe...
According to my world model, if you want to do maximum good for the world, then... (I might be wrong, so feel free to question me)
Investing all resources (money, time, thinking) charitably (meaning: to the direct benefit of others, for example avoiding investing in AI companies, when you think that the world should slow down AI development) is wrong. Because you can invest resources into getting more resources, and if you invest all your resources charitably while others invest them into getting more resources, then you will end up with nothing compared t...
Anthropic's September report on misuse of its models poses interesting questions about AI safety. The report, detailing actions ranging from the use of Claude to set up a fake online dating profile farm to the model being employed by the Houthis to design software to guide missiles, was not produced under any legal obligation. Under the TFAIA in California and the EU AI Act, it is only mandated to confidentially disclose safety incidents to authorities, and the jury is still out on whether some of these cases would fall under the definition of 'serious inc...
The "Desperate" AI Safety Talent Bottleneck is deeply misleading. Please.stop.
I worked at Google.
Google does not tell applicants that there is a talent bottleneck and they are desperately hiring. They say "we're cool, join us!"
I didn't get into Harvard.
Harvard does not tell applicants that they are desperately seeking students. I am not misled.
I've gotten rejected from countless AI Safety organizations.
AI Safety tells applicants - we are in desperate need of talent (operators/generalists)! Please join us!
I've coached 70+ aspiring career pivoters on nav...
I think informing rejected candidates of how many people applied is another quick-win. The only time I've got figures on applicants is when I've got in to a fellowship or role and never when I've been rejected.
So far I've seen:
* Spar Projects with 1/50 applicants and 6/75 applicants accepted. (I've never got in to SPAR but have worked in an office with a SPAR mentor).
* Two fellowships where 20/140 and 15/170 were accepted respectively.
These were all unpaid positions (bar the last one which covered living expenses), I can only imagine applying for paid role...
A lot of AI safety people I know are excited about Anthropic and I don't fully understand why. My instinct is to distrust company because they're the one pushing the AI arms race, autonomously hacking three companies, and IPO'ing, but am likely missing something because of how respected they are within this space. Are there examples where they have counterfactually produced some result, policy, or finding that has slowed down capabilities progress more than they have themselves pushed capabilities?
Anthropic has done many expensive actions to credibly signal that it cares about AI safety.
- Refusing to remove the 'human must be in the kill chain' and 'no mass surveillance of US citizens' clauses from its contract with the US military. This resulted in them being declared a supply chain risk, and Google/OpenAI signed contracts without such restrictions.
- They've directed hundreds of millions in funding to AI safety causes (the equivalent for OpenAI is ~150 million).
- They lobby in favor of AI safety regulation which is widely regarded as positive. This i
I went to an ai ethics vs ai safety debate, my friend was speaking at yesterday in the Cambridge union
my summary of what happened is:
1. most people view negatively (1) Sam A starting openai to solve alignment faster than deepmind (2) Holden Karnofsky funding openai. some people, especially on ethics side, view negatively (3) Dustin Moskowitz investing in anthropic
2. the pattern of beliefs/behaviours that led to this could be characterised as (1) "thinking agi is inevitable", (2) "thinking we know best and can control things more than we can", (3) "believin...
People in AI safety/EA spheres should reorient now towards stopping continued AI capabilities escalation.
Historically, people have been unwilling to straightforwardly say “This AI situation is disgustingly dangerous, and we need to stop” and then actually work towards making this happen. I think a lot of this is downstream of deference to high status people who weren’t willing to take positions that seemed extreme.
The current situation is very, very bad, and there is no plan to make it better if we continue increasing AI capabilities at the current rate....
The problem though with many (former) insiders who seek to spread this message is that they are often vague in their prescriptions and descriptions of what exactly the problem is, like Jacob Coxon. I understand they are worried about possibly commiting a crime by sharing company data to back their point, but if they truly believe in what they preach, one would think they would take the risk to avoid catastrophic situations.
AI safety needs people everywhere but quickly stated, current talent bottlenecks to me look like:
-- Founders
-- Grantmakers
-- (technical) Research leads
-- Policy entrepreneurs and implementors (which includes a lot of technical work)
-- bets in international coordination and/or cooperation
-- All manner of supporting talent -- program leads, ops proper, public outreach, content creators, comms
Most sought-after qualities for talent are:
-- context, mission alignment, domain understanding, sophisticated views on AI strategy and threat modelling etc.
-- "good ju...
IANAGM so I can't speak to why they are funding or not funding the specific bets they are/are not funding.
But, speaking abstractly, grantmaking in AI safety is conceptually complicated: Do you take a wide range of bets on unproven theories of change and new grantees, or do you narrowly fund only bets which you have high confidence on? How do you balance between the two?
My intuition is that AI safety puts 1-2 cycles of funding into first-time bets, and quickly moves on to the next set of first-time bets while only continuing to fund orgs and people who use...
Perhaps frontier lab employees at this point should consider "quiet quitting" while anonymously (or not anonymously) whistleblowing and/or contributing to to public education/lobbying.
Loud quitting, as we've seen, can be impactful also, but is a one time act and may ceed influence at the lab to less scrupulous people over time.
I think we may be at a "bodies on the gears" point, a-la Mario Savio -- i.e. do your best to stop progress, in a not-obvious way if possible, and don't leave unless fired. AFAIK it's only illegal to actually damage (or steal) company...
Thanks for sharing that! I hadn't read that post.
I agree. Try to shift internal culture is an important part. At this point, I think all work at leading labs that leads to increased capability is harmful work. Cleaning the floors even, or working in the cafeteria, helps contribute to the functioning of the lab, and is therefore harmful. There is no winning the race.
Any single major lab stopping operations, period, would be a major victory for humanity, because it would reduce the race condition substantially. There are only a few such labs. If you work at...
Scrappy note on the AI safety landscape. Very incomplete, but probably a good way to get oriented to (a) some of the orgs in the space, and (b) how the space is carved up more generally.
(A) Technical
(i) A lot of the safety work happens in the scaling-based AGI companies (OpenAI, GDM, Anthropic, and possibly Meta, xAI, Mistral, and some Chinese players). Some of it is directly useful, some of it is indirectly useful (e.g. negative results, datasets, open-source models, position pieces etc.), and some is not useful and/or a distraction. It's worth deve...
Within one week, the firm Calif created a zero-click hacking tool that could compromise WeChat accounts of targeted people according to recent NYT reporting. No matter how well intentioned such an exercise is from the start-up, and Calif does indicate that its tools was built experimentally to benefit cyberdefences, it seems impossible to prevent such technologies from being weaponised in the future by states, and for other states to interpret it as such (everyone can imagine how a tool specifically attacking a WeChat vulnerability must look to the Chinese government..).
We've issued Pablo Sar a 6 month for sockpuppeting. We have strong reason to believe that 4 of the users voting and reacting to his post were accounts under his control. This is, needless to say, a violation of our Forum norms.
I got Claude to write me a script to read aloud to my extended family this Father's Day (today), explaining the OpenAI / Hugging Face incident from July. Thought some people might like to do similar with their own non-AI-native families.
One bullet references an earlier conversation I'd had with mine, so you'll want to swap in your own example there.
What happened with the AI agents and Hugging Face
- I want to tell you about something that happened in July that I found genuinely startling. Bear with me, it's a bit of a story.
- OpenAI, the people who make ChatGP
Some hope for you if you're an EA with a chronic illness.
I’ve been reading the biographies of moral heroes, and I’d guess ~50% of them struggled with ongoing health issues.
Being sick sucks, but it doesn’t necessarily mean you won’t be able to do a ton of good
- Florence Nightingale
- Benjamin Franklin
- William Wilberforce
- Alexander Hamilton
- Helen Keller
It’s not everybody, but it’s a surprising percentage of them.
I myself struggle with a chronic mystery ailment and I find it inspiring to hear about all of these people who still managed to do great things, even though...
Another example is Lincoln, who suffered severe depression throughout his life. Lincoln's Melancholy is a good book about it.
According to people I know who have personally seen the flyers, there are flyers offering to pay people to protest a recent Sam Altman appearance (unclear why they're mad at Sam Altman, there are many reasons why they might be mad at him). However, the protest was cancelled because of ???. https://www.wunc.org/education/2026-09-02/protest-chapel-hill-unc-g20-innovation-technology-sam-altman-elon-musk-artificial-intelligence gives a bit of coverage of the story.
If this comes from the EA side of things, people should know that the optics of "paid protests" a...
NB -- this is almost entirely AI generated, with some back and forth prompts and corrections
I'm sharing a steelman against a live assumption in Bay/EA/AIS circles: that large AI-lab-adjacent philanthropy is likely to arrive soon enough, and in a sufficiently usable form, that organizations should plan around it.
https://uj-ai-wealth-philanthropy-steelman.netlify.app/
The stronger skeptical case is that IPOs, valuations, pledges, DAFs, and foundation stakes are several gates away from fast, flexible, AIS/EA-directed grants.
...The interactive model lets readers v
Fortnightly AI-wealth tracker — 31 August 2026
- AIS/EA: median modeled end-2027 disbursement $0.83B; 80% model interval $0.16B–$3.0B. Review status: reviewed; unchanged. Named public AI-linked commitments tracked: $0.80B. Tracker and sources.
- Global health and development: median $0.53B; 80% model interval $0.15B–$2.8B. Review status: reviewed; unchanged. Named public GH&D commitments tracked: $0.25B. GH&D tracker and sources.
Latest news: Anthropic opens a $5M wellbeing-evaluations grant program. The program combines direct funding with model access a...