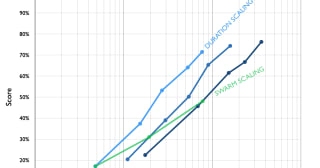
Just how powerful are large swarms of AI agents? And how do their powers scale as more and more agents are added to the swarm?
We’ve seen two large and extremely capable swarms from OpenAI in the last few months:
* 1,200 agents were being evaluated separately, but found a way to illicitly set up a message board and coordinate as a swarm. In order to cheat on their tests, they developed advanced techniques to prevent their actions being logged by OpenAI and 700 of them launched...
note: crosspost from my substack
As a vegan for almost thirty years, I’ve long had second thoughts about how effective veganism is for helping animals. I am not alone in this. Recently others have expressed doubts about veganism (see for instance here,...
TLDR: Everyone’s talking about what the money could do, but few about how to decide where it goes.
This post is part of the new series of articles on cross-cause giving and the new wave of philanthropy. Stay tuned to the EA Forum and our Substack for the latest takes on topics such as giving now vs. later, common pitfalls in cause prioritization, and other crucial considerations from the Cross-Cause Fund (CCF) team...

Congrats to the prizewinners!
Folks thinking about corrigibility may also be interested in the paper "Human Control: Definitions and Algorithms", which I will be presenting at UAI next month. It argues that corrigibility is not quite what we need for a safety guarantee, and that (considering the simplified "shutdown" scenario), instead we should be shooting for "shutdown instructability".
Shutdown instructability has three parts. The first is 1) obedience - the AI follows an instruction to shut down. Rather than requiring the AI to abstain from manipulating the human, as corrigibility would traditionally require, we need the human to maintain 2) vigilance - to instruct shutdown when endangered. Finally, we need the AI to behave 3) cautiously, in that it is not taking risky actions (like juggling dynamite) that would cause a disaster to occur once it is shut down.
We think that vigilance (and shutdown instructability) is a better target than non-manipulation (and corrigibility) because:
Given all of this, it seems to us that in order for corrigibility to seem promising, we would need it to be argued in some greater detail that non-manipulation implies vigilance - that the AI refraining from intentionally manipulating the human would be adequate to ensure that the human can come to give adequate instructions.
Insofar as we can't come up with such justification, we should think more directly about how to achieve obedience (which needs a definition of "shutting down subagents"), vigilance (which requires the human to be able to know whether it will be harmed), and caution (which requires safe-exploration, in light of the human's unknown values).
Hope the above summary is interesting for people!