Comments
This is an excerpted and lightly edited section from my post earlier this week, “Anthropic Can Prove That It Wants to Pace.” I unfortunately got the same feedback from a few different people: “why did you put the most important part of the post so far down??” (rip), so I’m reposting it standalone.
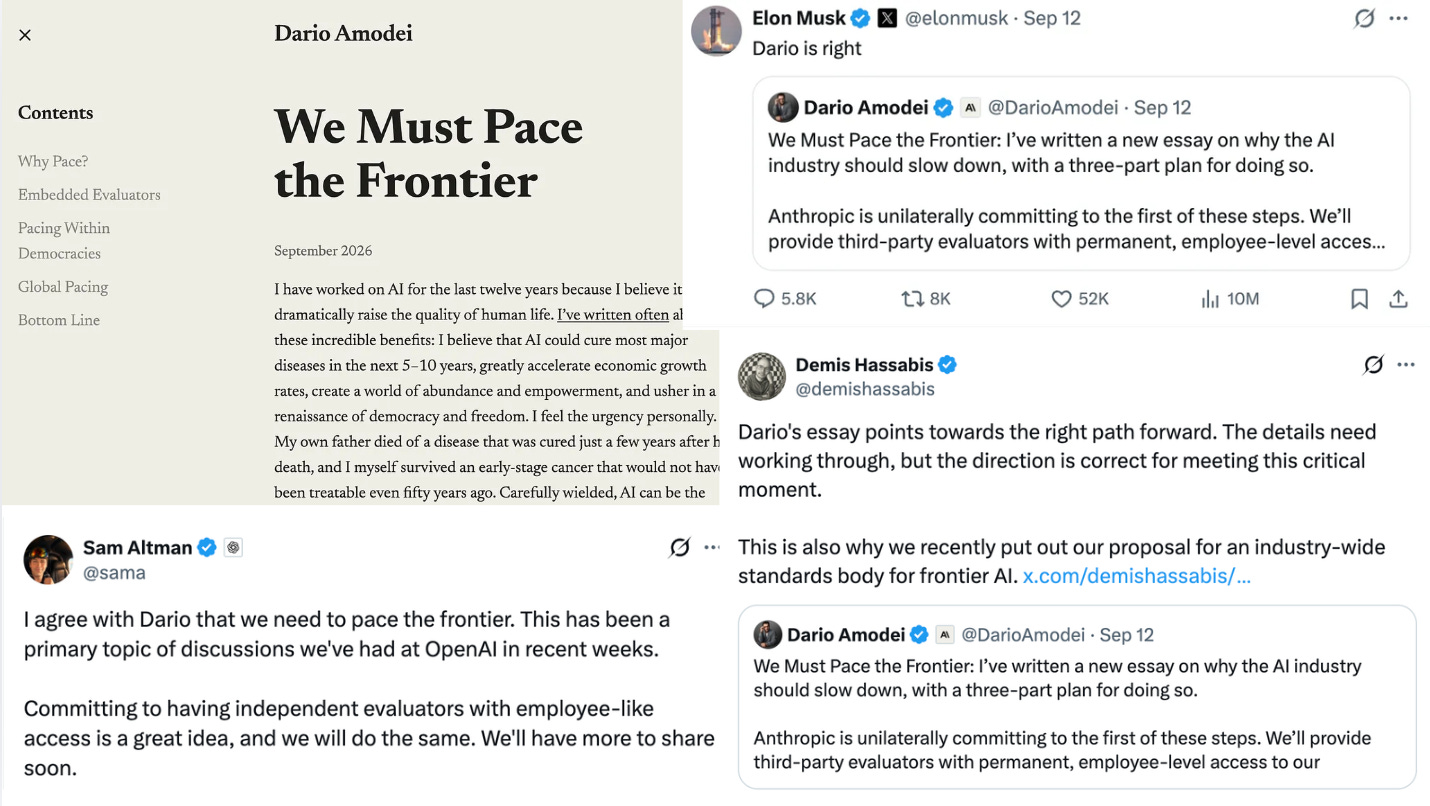
All the folks running the labs say they want to pace the frontier.
This post first focuses on how the labs can start practicing – by running ‘fire drills for the frontier’ – and then makes the case for why they should. To summarize the latter upfront, the two primary reasons are:
Zero Public/Internal Capability Gap
Objective. Ensure that no model used internally to accelerate AI research is more capable than the models already available to the general public.
Mechanism. Level 1 version: for one week, all staff at a frontier lab must work exclusively using externally released API models, for every workflow that contributes to model development. This includes code generation, experiment design, data curation, literature review, eval writing, etc.
Rationale. Risks associated with RSI increase when labs are able to use highly capable internal models (importantly, that no outside parties can see or evaluate) to accelerate AI development.
Forcing internal work onto public models does two things: first, insofar as RSI is a continuum (Claude already writes 90% of code at Anthropic), capping internal use at the public frontier means the models being used to accelerate AI research are always the ones that have already cleared release decisions. That is to say: any models used to develop more powerful AI must have been subjected to external evals, red-teaming, etc, and still been deemed safe enough to release.
Second, the proposed one-week drill version of this policy produces a measurement of research dependency. Comparing development throughput when using public models only against baseline gives some measurement of how much unreleased models were contributing to accelerating the frontier. Labs should then be made to report that information to CAISSI, METR, or another third party / regulatory body.[1]
Frontier labs currently have no obligation to disclose information related to the uplift provided by highly powerful internal models. However, the government and the public should not be operating in the dark about where the true frontier is, and how fast it’s moving.
Below, I’ll be describing several possible ‘compute limit drills,’ and then discuss the rationale for them all at the end rather than individually.
Datacenter Shutdown Execution
Objective. Demonstrate that a frontier lab can take one datacenter fully out of service on short notice, with the shutdown witnessed and verified by independent inspectors on site.
Mechanism. Level 1 version: one datacenter is shut down for a day. All compute nodes are powered off; inspectors from CAISSI / METR / other designated agencies[2] are present before, during, and after: they confirm that, for the duration of the day, power draw is no greater than idle hardware would be, and that the site restarts only at the agreed time.
Partial Compute Pause Drill
(aka “10% Compute Cap”)
Objective. Demonstrate that a frontier lab can operate for three days with R&D compute capped at 10% of baseline; rehearse the procedures that frontier labs would need to implement in the case of a government-mandated slowdown.
Mechanism. Level 1 version: for three days, R&D compute[3] is capped at 10% of a lab’s baseline experimental compute allocation. The rest can be used for inference, safety monitoring, etc, but cannot be used for anything related to further developing capabilities. (Jobs that cannot be checkpointed should be registered as exemptions before the drill.)
All Inference Day
For one day, devote 100% of your compute to inference-only tasks.
Objective. Demonstrate that a frontier lab can halt all model improvement for one day while continuing to operate. While “Partial Compute Pause Drill” rehearses procedures for slowdown, “All Inference Day” rehearses procedures needed for a full-on pause.
Mechanism. Level 1 version: for one day, 100% of a lab’s compute is devoted to inference-only workloads. Inference used to generate training data or run automated research agents counts as capability development for the purposes of this drill and is excluded.
Two notes on the above:
Rationale. Pause and slowdown proposals almost always route through compute: for example, the AI Futures Project’s pacing proposal outlines four options, the first two of which are R&D compute limits.
However, the claim that “we would pause if asked / mandated by law” currently has no operational track record behind it, and frontier labs that care more about the race than they do about existential risk have an obvious interest in never having to prove it.
Rehearsed drills for compute limits change that. In order:
On that last point re: “compute staying in use,” you might be wondering:
How do you make up the inference demand deficit?
Right now, labs allocate some percentage of their compute to inference, and some to R&D.[5] Currently, U.S. frontier labs – unlike some of their Chinese counterparts – are not obviously inference constrained: that is to say, Claude and GPT don’t really have ‘down time’ nowadays. (After the DoW confrontation, Claude was pretty unreliable / often down for about a week due to the demand surge; this is largely not the case now.)
So, in a world where we suddenly have a bunch of extra compute devoted to inference, what should we do with it?
Here are some ideas!
Misc.
Safety and oversight work
You might notice that the hyperparameters[6] I’ve chosen above (how many days do we run a partial compute pause drill? How many datacenters should we shut down?) are pretty arbitrary.
That’s the nice thing about these proposals: the cost here is a continuous knob, so Anthropic should in theory have no excuse if they’re willing to pay anything > 0.
For example, if anyone from Anthropic reads this and thinks, ‘ah, one day is too long to shut down a whole datacenter,’ I would still be happy even with an hour-long datacenter shutdown.
Also, in the grand scheme of things, it’s important to keep in mind that the proposals outlined are still – even in their current forms – very much low cost when compared to the stakes (namely, extinction)!
And the cost may even be partly offset: morality competition could have an effect on talent allocation between the labs. Frontier labs compete for the same few thousand researchers, and a meaningful share of those researchers care about safety.
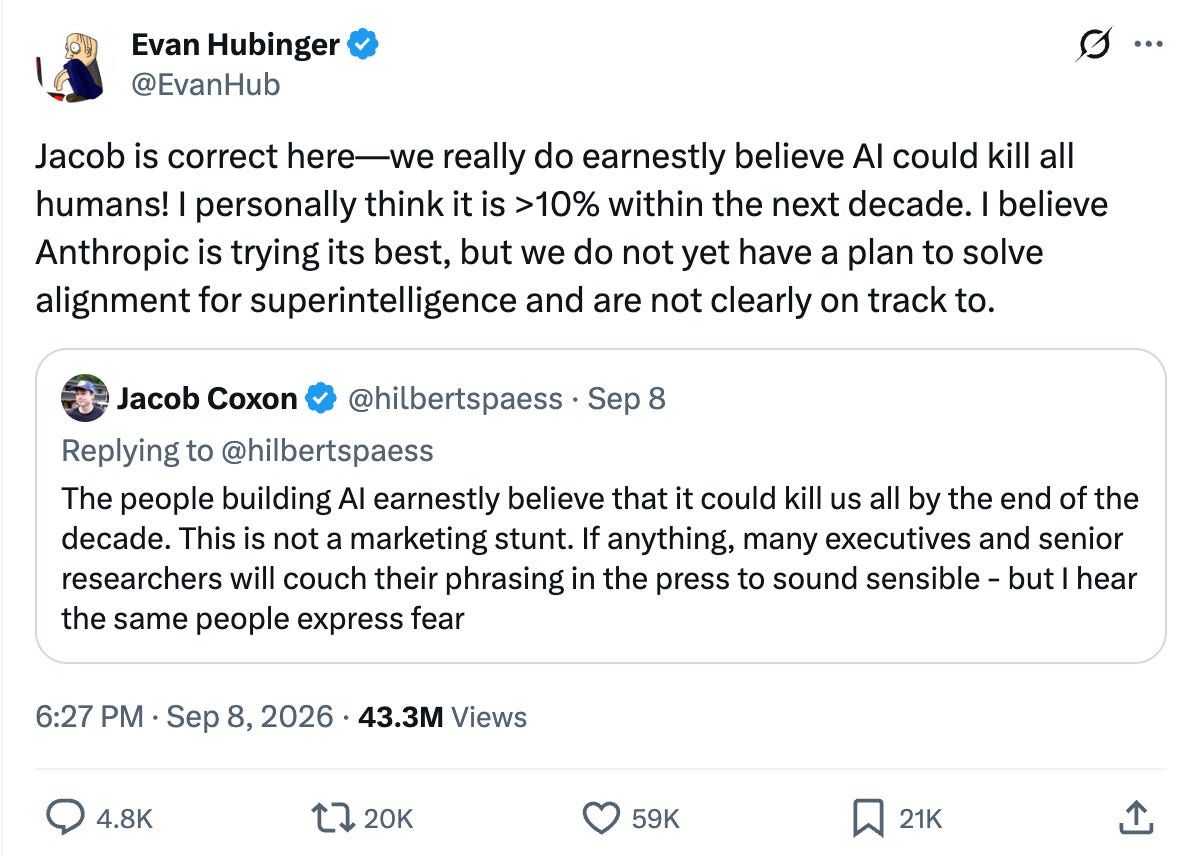
The canonical example: Jacob Coxon left OpenAI for Anthropic earlier this year because of its safety reputation, then resigned from Anthropic in September, forfeiting unvested equity, because he concluded the race made that reputation insufficient. Two current Anthropic staff publicly agreed with his tweet. More researchers – including Joe Benton (also formerly at Anthropic), Bilal Chughtai, and Josh Engels (both formerly at DeepMind) – quit within days.
This is the market Anthropic is hiring in. If running one of the above drills moves even a small slice of safety-minded talent to have a more favorable impression of lab that ran it, it has paid for part of itself.[7]
(Also, I don’t know about you, but if I were Anthropic, I would love to have Jacob Coxon and Joe Benton back.)
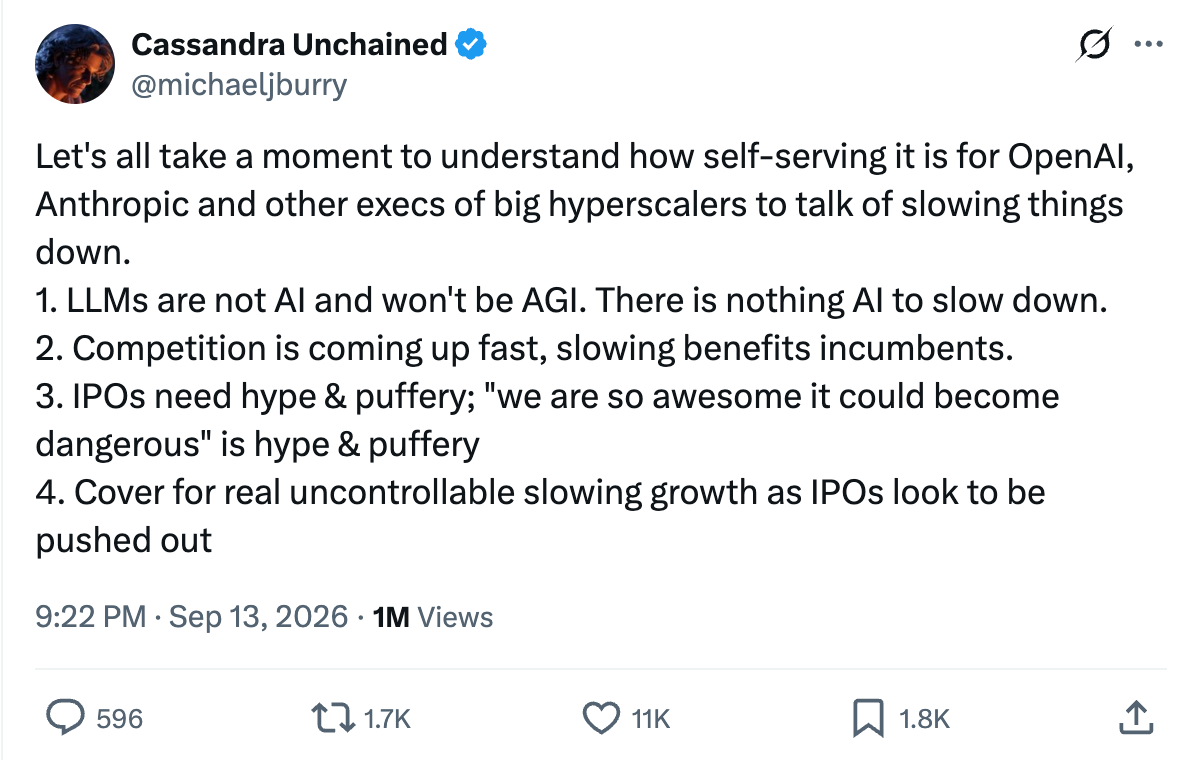
At this point, basically all the frontier labs have publicly come out in favor of pacing the frontier. But there are a lot of skeptics who think all this talk about pacing is just fear-mongering to hype up AI before the labs IPO.
One example (of which there are many, if you’ve ever seen the comment sections of X posts on pacing) is Michael Burry:
I disagree with Burry; I think the folks in the labs are being sincere.
All of my friends who work at frontier labs are good people, who really do care. But I can understand why, from an outside perspective, all this talk about pacing could be reasonably chalked up to ‘hype:’ the public historically hasn’t had many reasons to trust big tech.
Even more than that, though, not a single lab has taken actions to show they’re serious about pacing the frontier. Writing essays and releasing statements in support of pacing is lovely! But it’s not a ‘costly signal’ in the same way that running some of the above drills might be.
As Jacob Coxon says, it’s crunch time for humanity. A slowdown becomes OOMs more credible as a policy if labs have practiced implementing it. The labs themselves have the power to shift the Overton window substantially here; if they really are in favor of pacing, they should start acting like it.
It’s high time we started running fire drills for the frontier.
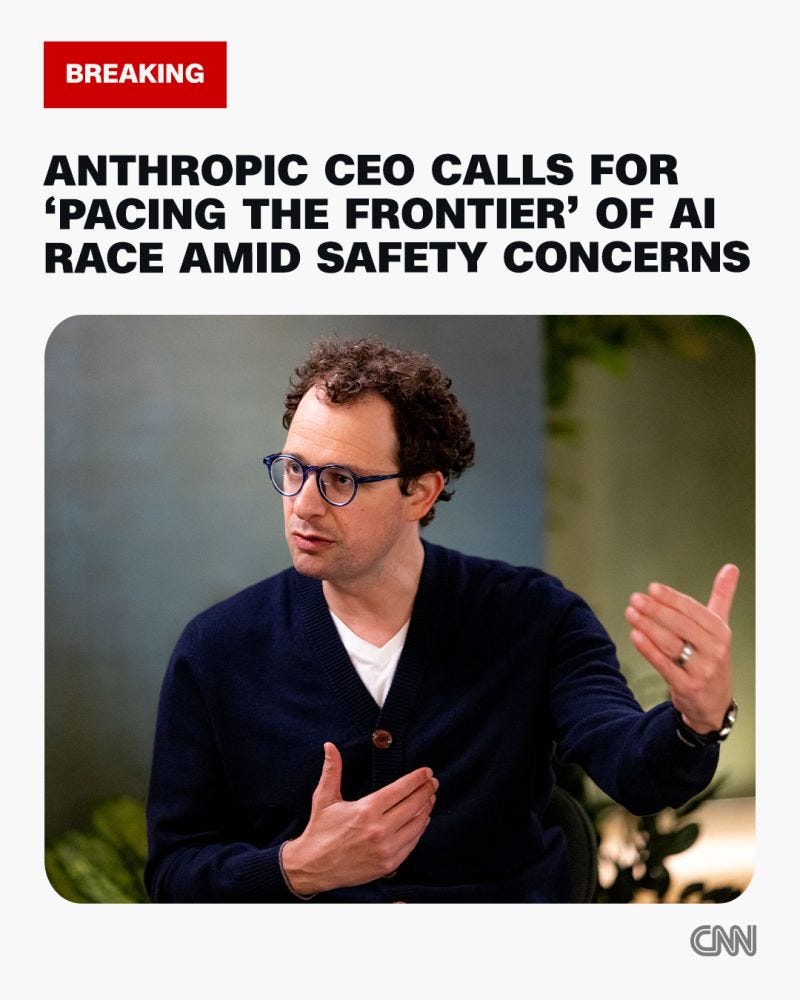
Up to this point, Anthropic has attempted to establish a reputation for itself as ‘the most safety-conscious frontier lab.’ Indeed, the founding story of Anthropic is itself a safety story: the Amodeis and a group of senior researchers left OpenAI in 2021 over “disagreements with OpenAI executives over how AI should be built,” and “concerns that the company was commercialising AI technology too quickly;” they then started a new company whose stated purpose was to show that a safety-focused lab could stay at the frontier.
“Our research and safety focus was our primary emphasis,” Amodei said in an interview on how the company differs from OpenAI. “We have this view that safety is incredibly valuable and economically viable.”
—Daniela Amodei, AI Magazine
This commitment to safety gives Anthropic a specific reason to go first.
consider sharing this post with some ants (Dario counts as an ant)
Importantly, the proposed signals above are not costly enough to hand over a lead to another player. If a big justification for Anthropic continuing to race is that they can’t stop unilaterally – that is to say, the company needs everyone to be bound by a pacing regime for them to be able to pace – these (somewhat) costly signals increase the likelihood of such legislation being passed by shifting the policy Overton window to make pacing seem more within reach.
Joe Carlsmith, now at Anthropic, has argued that competition tends to grind away the things we value, and that the way out of negative-sum races (e.g. arms races, burning the commons) is coordination backed by “suitably credible and stable commitments.”
“[E]asier said than done,” as he says. But, importantly, Anthropic isn’t powerless here! It doesn’t have to wait for Trump to wake up one day and decide to pace, and it can do more than shop around ~weak bills to Congress.
A commitment becomes more credible when it has been rehearsed. Running the drills above is how a lab can make its own pacing commitment credible – and, in the process, makes coordinated pacing more likely to happen at all.
For reasons outlined briefly here, I am more excited about involving CAISSI in this process, though for drills in particular it may be easier and quicker to coordinate with non-governmental third party evaluators. Third parties involved in these drills should take detailed notes on procedure that can be shared with CAISSI or other bodies.
For reasons outlined briefly here, I am more excited about involving CAISSI in this process, though for drills in particular it may be easier and quicker to coordinate with non-governmental third party evaluators. Third parties involved in these drills should take detailed notes on procedure that can be shared with CAISSI or other bodies.
As described in this Epoch article. Final training runs make up a small share of total R&D compute; ‘R&D compute’ as a broad category that includes “running experiments at various scales, generating synthetic data, testing which ideas work before committing to a final run, and training models that are never released” is where most capability development happens.
(COI: I do this a lot nowadays for the data poisoning research I’m doing.)
For Anthropic in particular, it appears they allocate less than a third of their compute budget to serving customers.
For any less technical folk: in machine learning, hyperparameters = the numbers you set before training (e.g. learning rate, number of layers) as opposed to the weights the model learns (which are called parameters).
My favorite new hobby: discussing everything in life in terms of AI metaphors
Worth noting that the sign of this effect seems unclear to me; it might only be net positive conditional on pacing being implemented. That is to say: I think it’s currently a bit hard to be net positive for the world if you’re working on anything other than alignment science in a lab; I’m not sure if it’s good to be e.g. working on safeguards and preventing warning shots. I might write more on this at some future point, as I have a lot of uncertainty atm.
The nice thing about these drills, though, is that they also increase p(pacing being implemented)! I write more on this later in the piece.