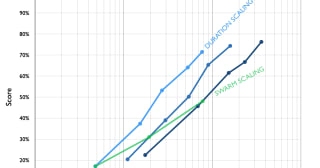
Just how powerful are large swarms of AI agents? And how do their powers scale as more and more agents are added to the swarm?
We’ve seen two large and extremely capable swarms from OpenAI in the last few months:
* 1,200 agents were being evaluated separately, but found a way to illicitly set up a message board and coordinate as a swarm. In order to cheat on their tests, they developed advanced techniques to prevent their actions being logged by OpenAI and 700 of them launched...
TLDR: Everyone’s talking about what the money could do, but few about how to decide where it goes.
This post is part of the new series of articles on cross-cause giving and the new wave of philanthropy. Stay tuned to the EA Forum and our Substack for the latest takes on topics such as giving now vs. later, common pitfalls in cause prioritization, and other crucial considerations from the Cross-Cause Fund (CCF) team...
Summary:
First, I give several different angles on how I feel about reinforcement learning:
* Theoretical case: RL is a black-box source of agency — this should give us classic misalignment worries, especially compared to agency-via-scaffolding
* Recent incidents (huggingface etc) and more mundane forms of misaligned behaviour in personal use give me bad vibes about the direction-of-travel of recent AI progress
* I’m worried things might get worse:...

I like this article and I agree with the argument in principle, but I'd like to see a bit more information presented about how the elasticity parameter is estimated.
In other words, what data has been used to compute this parameter? Experiments where people make choices among different lotteries? Implicit choices where people make tradeoffs involving risk? Stated preferences over comparisons of societal distributions of wealth?
I think it is mainly from individuals' explicit preferences over hypothetical gambles for income streams. e.g. if you are indifferent between a sure salary of $50,000 PA and a 50-50 gamble between a salary of $25,000 or one of $100,000, then that fits logarithmic utility (eta = 1). Note that while people's intuitions about such cases are far from perfect (e.g. they will have status quo bias) this methodology is actually very similar to that of QALYs/DALYs. But I imagine all methods you mention are used. Also other methods such as happiness surveys give results in the same ballpark. If asking about ideal societal distribution, then that is actually a somewhat different question as there could be additional moral reasons in favour of equality or priority to the worst off on top of diminishing marginal utility effects. Eta is typically intended to set aside such issues, though there are other tests to measure those.
Thank you Toby. The 'preference over gambles' as a way of measuring diminishing marginal utility will depend strongly on the expected utility maximization assumption; in practice, it could be vulnerable to reference-point effects I believe. (Also the logarithmic utility function is obviously an imposed parametric assumption, but a good start.)
Still, these approaches seem reasonable, especially insofar as broadly similar results come from varying contexts.