I find it interesting how he says that there is no such thing as AGI, but acknowledges that machines will "eventually surpass human intelligence in all domains where humans are intelligent" as that would meet most people's definition of AGI.
I also observe that he has framed his responses to safety on "How to solve the alignment problem?". I think this is important. It suggests that even people who think aligning AGI will be easy have started to think a bit more about this problem and I see this as a victory in and of itself.
I've been pretty confused by LeCun. I think he has seen AI do useful things to manage misinformation at Facebook so he's annoyed when people claim the risk model from AI is misinformation generation, which is fair. But then he suffers from a massive failure in imagination when it comes to every other risk model.
He seems to think: "We don't have to worry about alignment, because we align humans to be nice moral people and governments to be good via laws!" But this is just obviously silly: look at how many people hurt other people and how many governments have awful laws (that people break all the time anyway)! Not sure what's not clicking with him when his own analogies fall apart with 1 second of reflection.
I'm truly, deeply baffled by Yann LeCun's bizarre pronouncements about AI safety.
He talks about AI safety and alignment issues as if he's simply too stupid to understand the 'AI Doomer' concerns (including those shared by most EAs.) But he's clearly not stupid in terms of general intelligence -- his machine learning work has been cited over 300,000 times, with an h-index of 143 (which is very, very high).
So, is this just motivated reasoning by someone with very deep professional and financial incentives to promote AI capabilities research? His position as a Vice President, and Chief AI Scientist at Meta, suggests that he might have too much 'skin in the AI game' to be very critical. And yet, many other leading AI researchers and AI company CEOs have expressed serious concerns about AI extinction risk -- despite their skin in the game.
Anybody have any insights into why LeCun is so dismissive about AI X risk?
Isn't it the case that lots (in raw numbers, not %) of smart people believe irrational things (e.g. religion, health, climate, politics) all the time? When you consider the size of the AI field, there was going to be at least one LeCun right?
Yeah, fair point. But most such irrational beliefs tend to be somewhat outside smart people's fields of personal expertise. And smart people tend to update if they're exposed to a lot of skeptical feedback -- which LeCun has been, on Twitter. Yet he's dug in his heels, and become even more anti-safety in recent months.
Maybe in the grand scheme his personal views don't matter much. But to a psychologist like me, his behavior is both baffling and chilling.
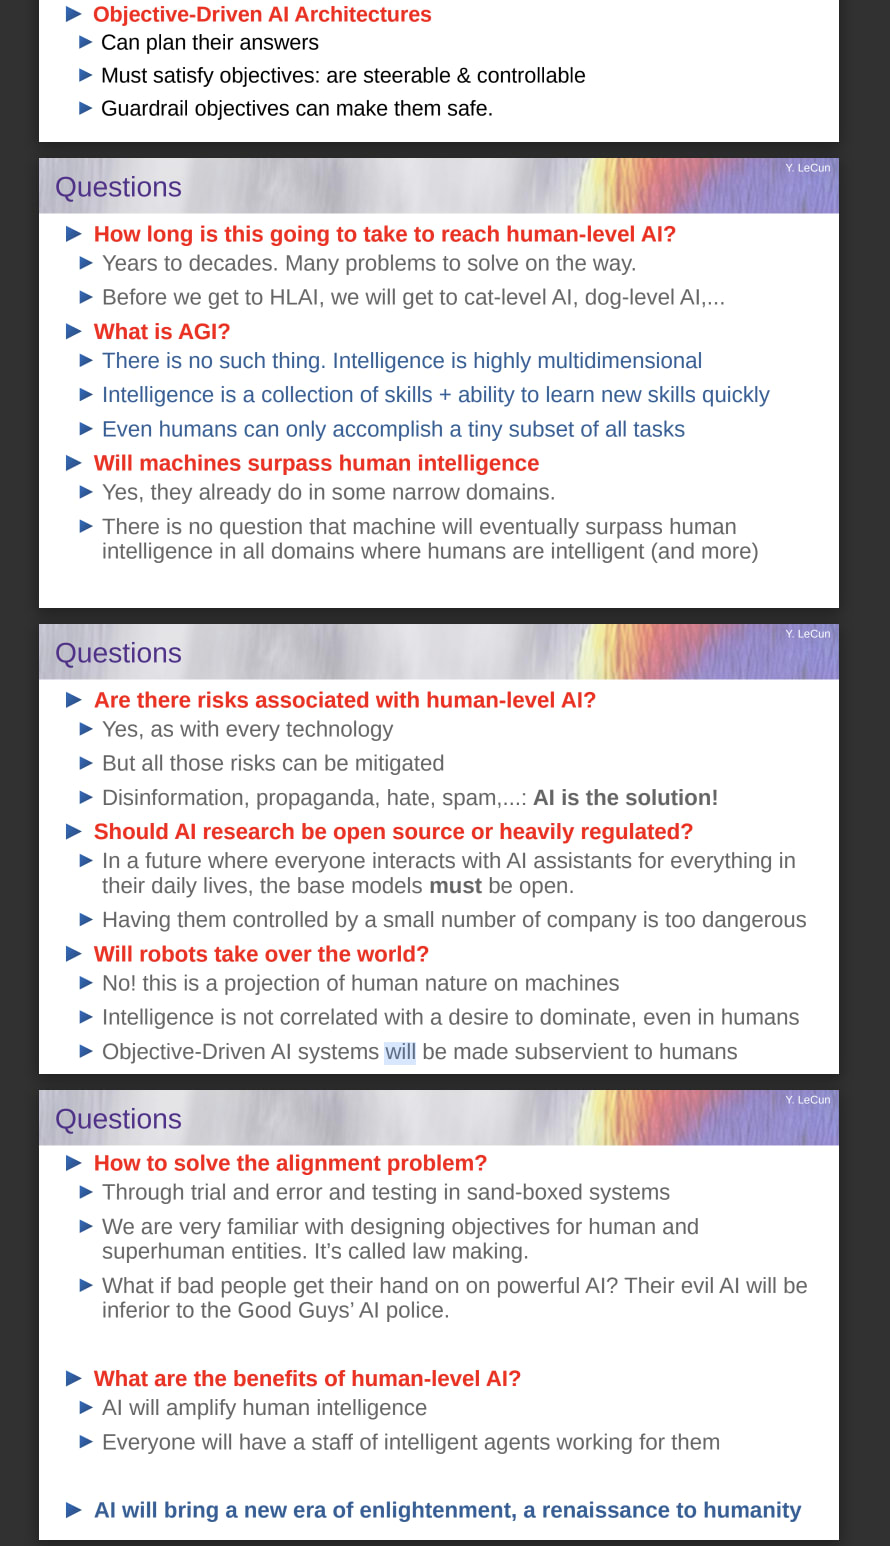
Yann recently gave a presentation at MIT on Objective-Driven AI with his specific proposal being based upon a Joint Embedding Predictive Architecture.
He claims that his proposal will make AI safe and steerable, so I thought it was worthwhile copying the slides at the end which provide a very quick and accessible overview of his perspective:
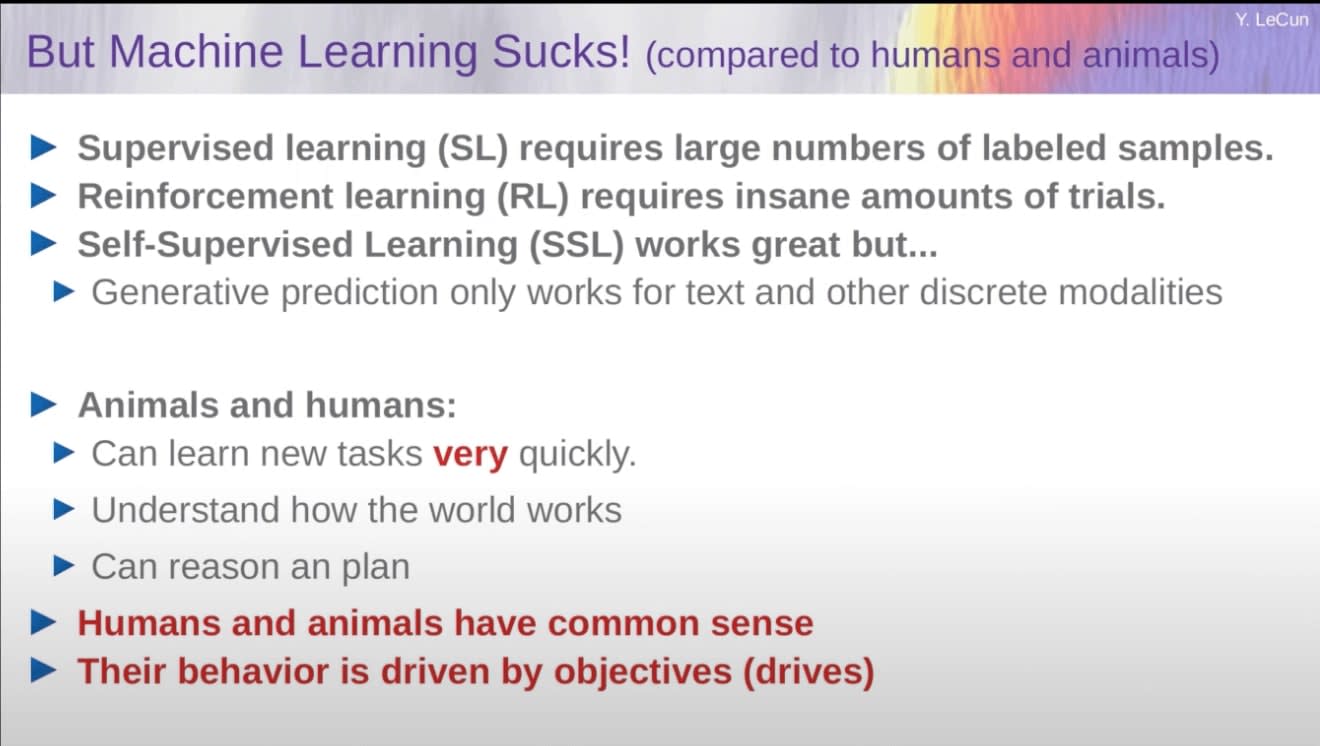
What does he mean by cat-level, dog-level ect? This slide may help[1]:
I find it interesting how he says that there is no such thing as AGI, but acknowledges that machines will "eventually surpass human intelligence in all domains where humans are intelligent" as that would meet most people's definition of AGI.
I also observe that he has framed his responses to safety on "How to solve the alignment problem?". I think this is important. It suggests that even people who think aligning AGI will be easy have started to think a bit more about this problem and I see this as a victory in and of itself.
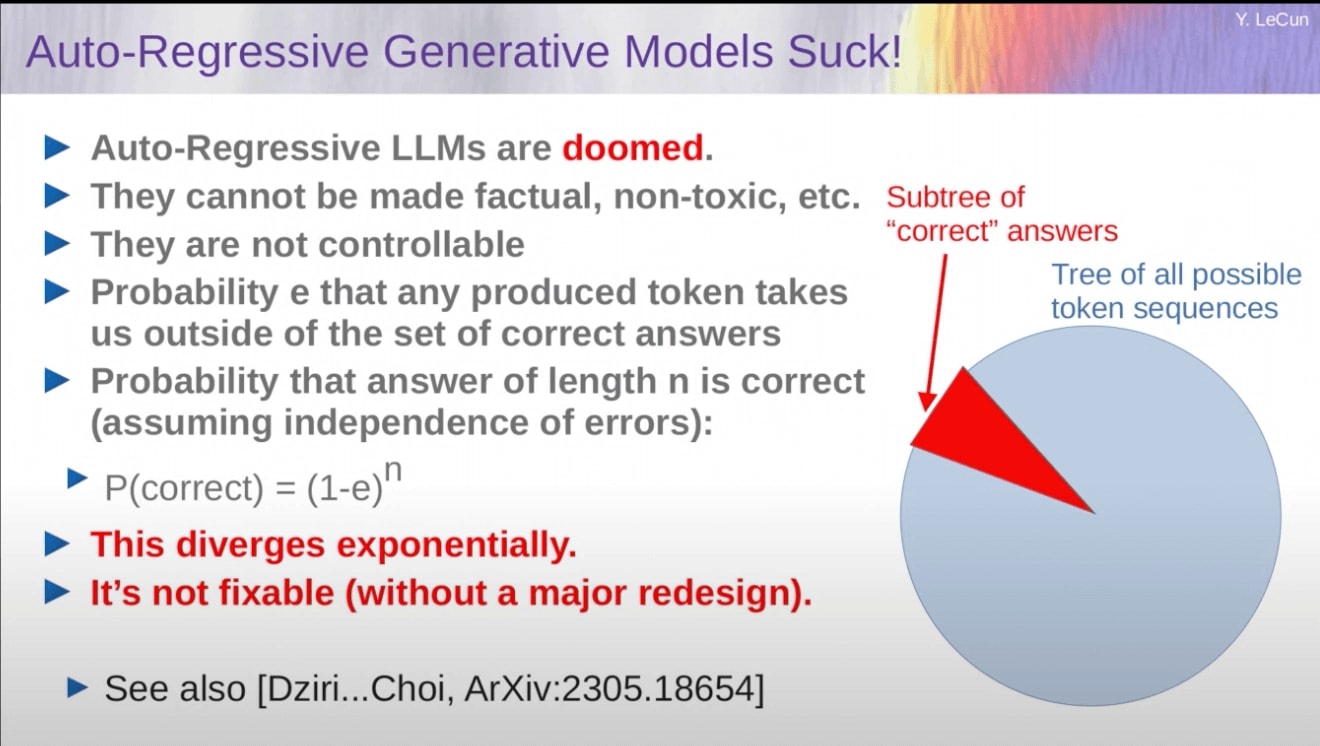
It's worth noting that he agrees with many AI safety folk that auto-regressive models are uncontrollable, he just thinks they aren't powerful enough to be a threat[2]:
Adam Jones' post provides a longer summary of why LeCun doesn't expect much from LLMs.
Worrying about superhuman AI alignment today is like worrying turbojet engine safety in 1920... Making AI safe is going to happen as with every new technology (e.g. cars, airplanes, etc): it's going to be a process of iterative refinement. And again, getting that slightly wrong may hurt some people (as cars and airplanes have) but will not wipe out humanity. I'm not saying it's going to be easy, just like making jetliners as reliable as they are today hasn't been easy. But making it sound like it's an unsolvable problem is, at the very least, extremely premature, and most likely just false. But regardless, until we have a semi credible design, we are discussing the sex of angels.
A preliminary estimate, and a request for better ones.
Summary
I believe the standard literature estimates for the number of DALYs attributable to a case of stunting are too low, largely because they don’t account for the long term effects. This means that childhood nutritional interventions that reduce the prevalence of stunting may be substantially more cost-effective than previously believed.
Epistemic status
Exploratory and back-o...
I’ve been feeling pretty shaken since the METR report about the Hugging Face incident came out last week. Over the weekend, I wrote up some thoughts on how lonely the AI situation sometimes feels to me. It’s more personal than what I’d usually share publicly, but I thought I’d post it here in case it resonates with anyone else.
I’m very grateful to the man...
TL;DR: Kairos has raised $50 million from Coefficient Giving for two years of funding, one of the largest commitments they’ve made towards AI safety fieldbuilding to date. We’re using this to make an ambitious push for growing Kairos, broadening our portfolio of talent infrastructure projects and incubating new organizations. We’ve doubled in size in the last six mon...


Thanks for sharing this! Good points here too:
I've been pretty confused by LeCun. I think he has seen AI do useful things to manage misinformation at Facebook so he's annoyed when people claim the risk model from AI is misinformation generation, which is fair. But then he suffers from a massive failure in imagination when it comes to every other risk model.
He seems to think: "We don't have to worry about alignment, because we align humans to be nice moral people and governments to be good via laws!" But this is just obviously silly: look at how many people hurt other people and how many governments have awful laws (that people break all the time anyway)! Not sure what's not clicking with him when his own analogies fall apart with 1 second of reflection.